AI Lip Sync
AI Lip Sync:Turn a Photo Into a Talking Video
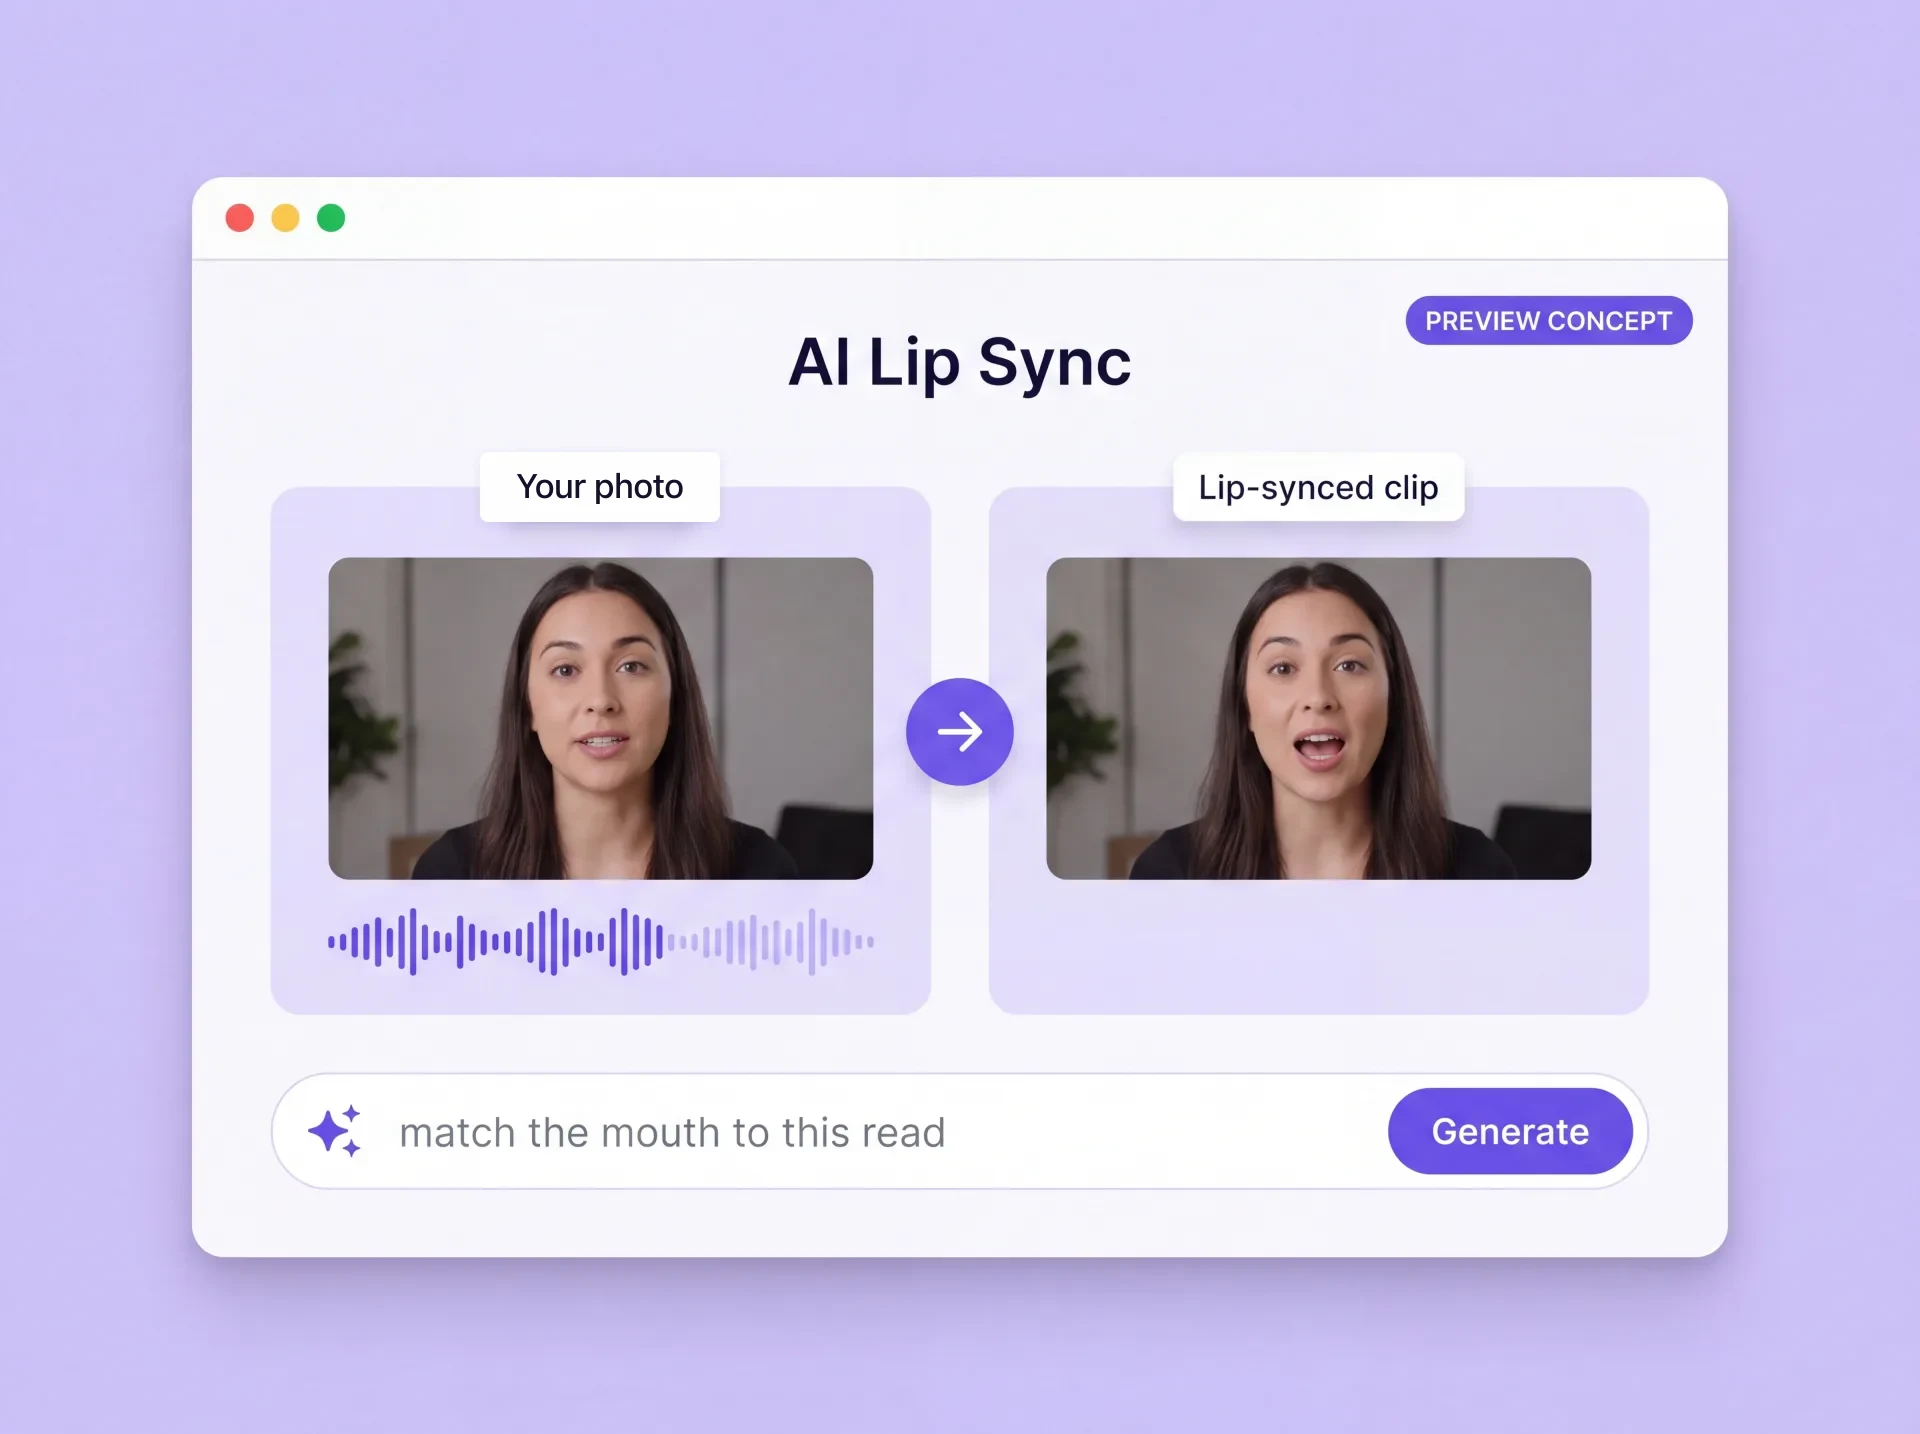
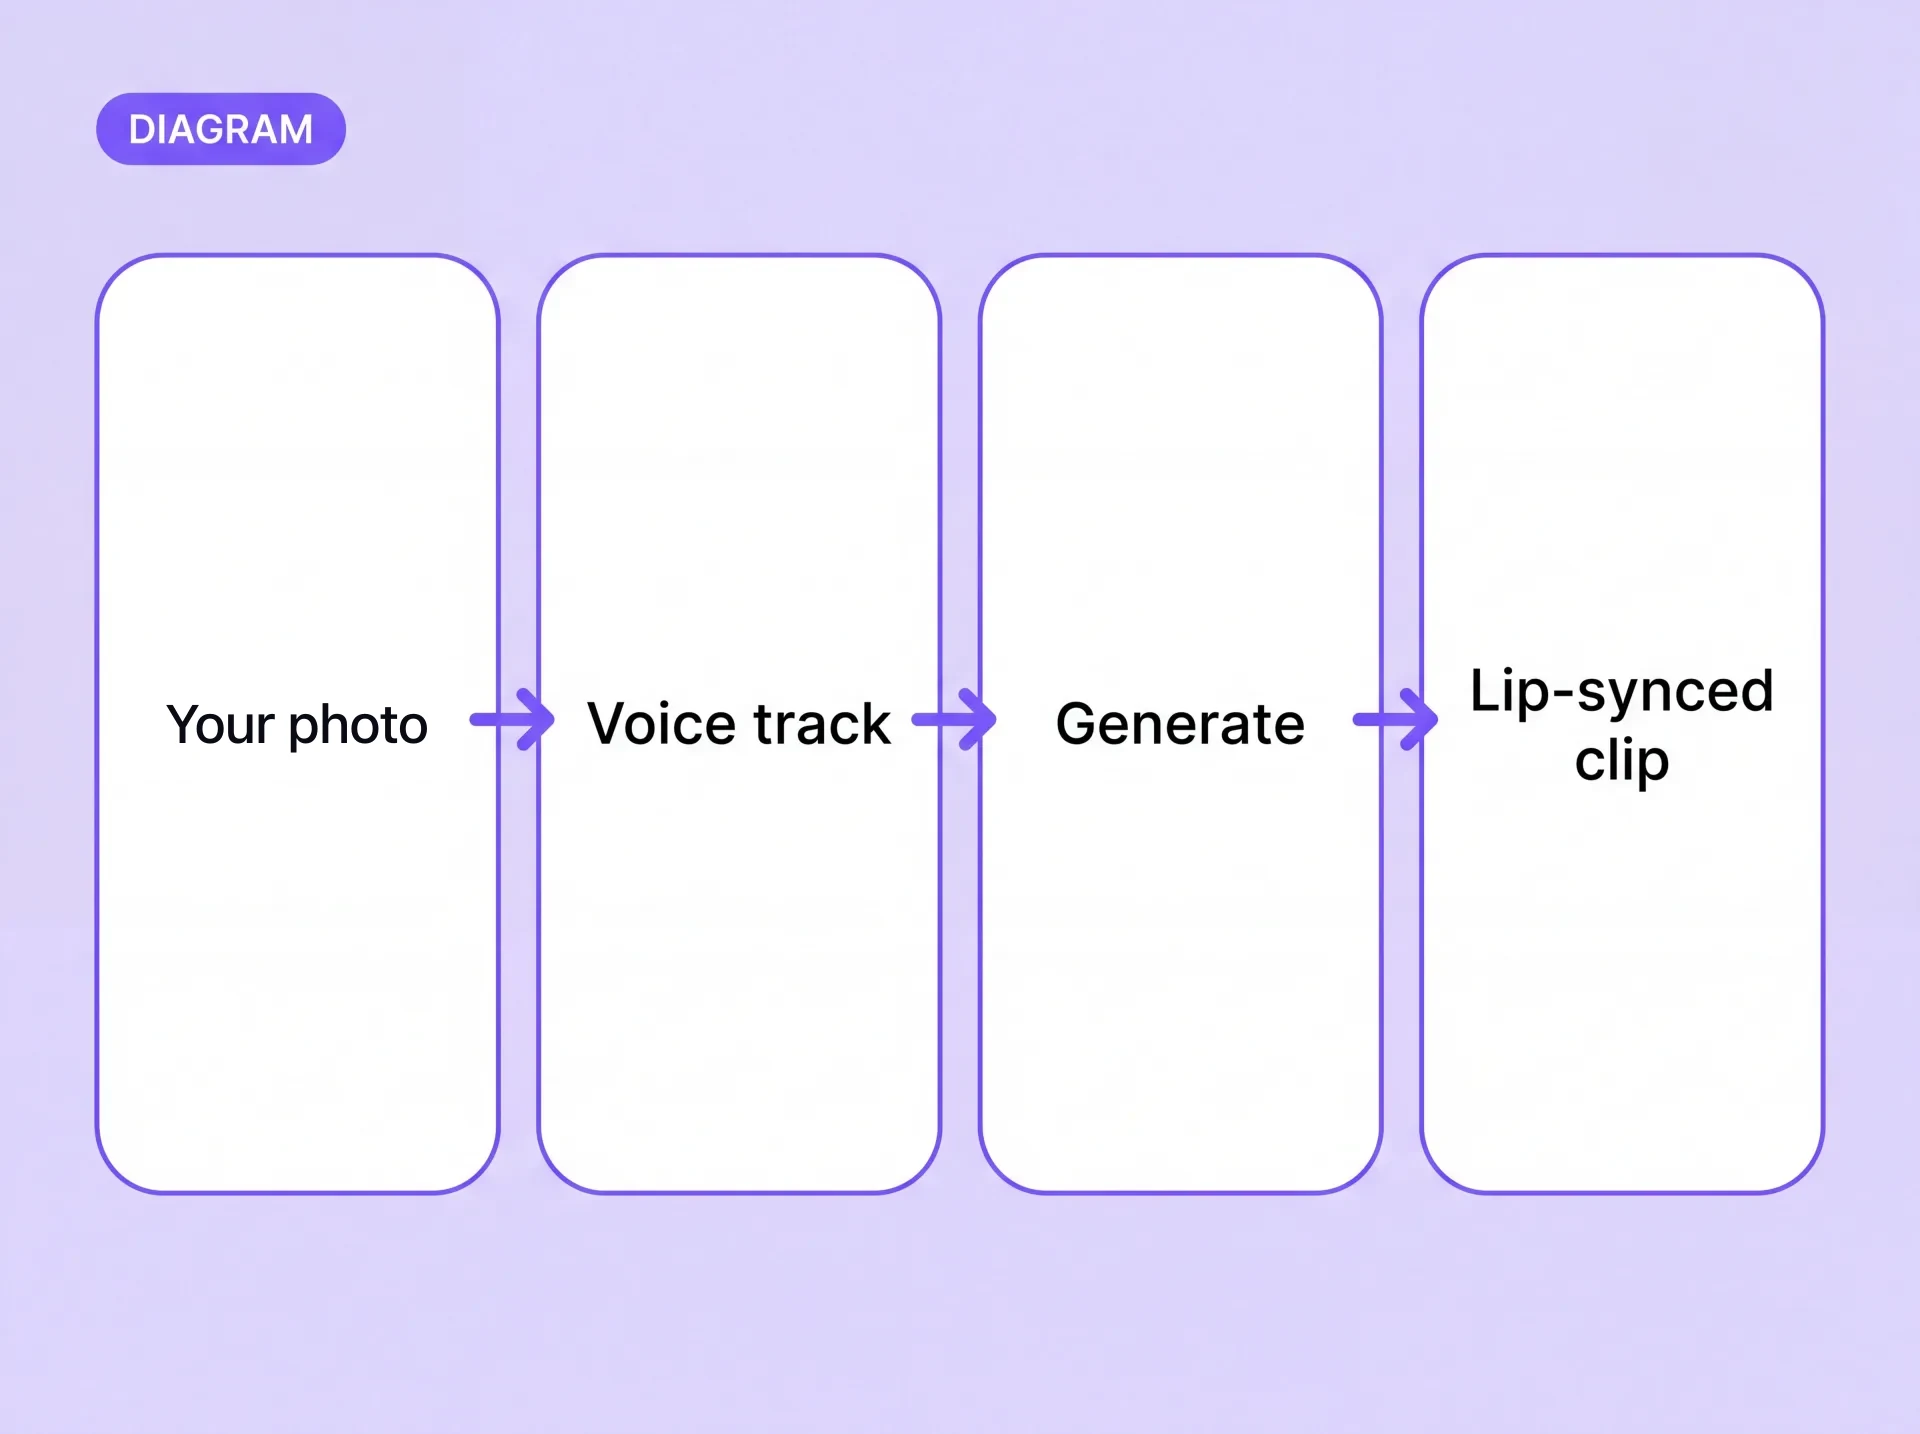
Upload a photo, add the voice track it should follow, and generate a video where the mouth movement matches the audio.
Credits never expire
What AI lip sync does
Lip sync in ZenCreator takes one photo plus the voice track you want it to follow, and returns a video whose mouth movement matches that audio. Timing is generated against your audio rather than keyed by hand, so there is no mouth-shape set to build and no waveform to scrub. You will also see it written as one word, lipsync.
This is a generative workflow rather than a frame-by-frame editor: the tool generates a new video from your photo instead of adjusting pixels in an existing one. That is why the result depends on the photo, the audio, and the optional prompt — a sharp, well-lit portrait and a clean read give the tool more to work with than a soft, low-light photo. Review the generated version before it goes into your edit.
AI talking photo: turn a portrait into a talking video
Upload one portrait and your own audio file (MP3 or WAV), and ZenCreator turns them into a talking photo: a video in which the lips follow your audio and the expressions follow what is being said, not just the sounds. An optional prompt sets how the words are delivered.

Start with a clear portrait
The photo sets who is speaking: face, style, hair and lighting stay consistent through the video. Choose a sharp portrait of one person with the face uncovered. Use only photos and voices you have the rights and consent to use, never those of public figures or celebrities (see the Content Policy).
Add your voice to the picture
Your MP3 or WAV file sets what is said and when the lips move. Record clearly at a normal volume, without echo, background noise or music: a clean voice recording works best.
Set the tone with an optional prompt
Describe emotion, tone, head or camera movement, and the video follows it. The prompt shapes how the words are delivered; it cannot change who is in the photo or the timing of the lips.
Have a portrait and a recorded line ready? Turn them into a talking video in the LipSync tool.
Make your photo talkWhy the ZenCreator AI lip sync generator fits how you already work
Every reason below comes down to the same trade: the face stays, the words change.
Keep the face, change the words
You are not rebuilding a performer or booking a shoot. The photo you already have becomes the source, the new read becomes the target, and the generated video carries mouth movement that follows it. When the script changes again, the same photo is still usable, and reusing it helps keep one character consistent from video to video.
Timing you don't keyframe
Mouth movement is generated against the voice track you supply, so nobody places mouth shapes against a waveform or chases a drift that only shows up on playback. That removes the manual timing stage rather than making it quicker.
Nothing to install
Lip syncing happens in the ZenCreator studio in a desktop browser, on the same machine you already edit on. There is no plugin to maintain and no local build to keep in step with your operating system.
You set the run, then generate
You choose the settings the tool exposes for your photo and voice track, including an optional prompt for tone and movement, then start the generation. Because the result depends on the photo, the audio, and those settings, a second run with a different read or a cleaner source photo is a normal part of the job — not a sign something went wrong.
What a lip sync AI can do with a single photo
Direct the performance in a lip sync video
Write the prompt the way you would brief an actor: "Warm, sincere tone, soft smile, slight nod" for a friendly read, or "Dramatic close-up, slow emotional delivery, intense eye contact" for a monologue. Keep it in step with the audio — an energetic prompt over a calm read looks unnatural.
Change the dialogue without a reshoot
A line gets rewritten, or a script needs a second version. Upload the new voice track with the same photo and generate again: the face stays the same, and the mouth movement follows the new words instead of the old ones. Nobody has to step back in front of a camera.
Give a generated character a speaking take
If the character came out of a generation rather than a camera, it can still be the source. Create the portrait in the AI Photo Generator, supply the read, and the mouth movement is generated against that audio.
How lip sync works in ZenCreator
Where creators use it
Short-form and UGC
A hook that already performs needs new copy. Keep the same creator portrait, record the new line, and generate a lip sync video that carries the new script — no shoot day, no re-lighting, and the face your audience already responded to stays in place.
AI characters and virtual influencers
A recurring character has to speak on camera. Supply the character's portrait and the read you wrote for that episode, and the mouth movement is generated against your audio, so the character's speaking takes come out of the same workflow every time rather than being animated by hand for each new line. Reuse the same reference photo to keep the look consistent across episodes.
Social and performance marketing
Three script variants, one hero portrait. Run the same photo against each read and take three matching videos into testing instead of producing three separate shoots — the variable under test stays the copy rather than the production.
Music and song lip sync
A track needs a face to perform it. Pair a portrait with the vocal and add a prompt such as "Strong emotional delivery, rhythmic head movements matching the beat" to get a music-video style lip sync clip. Use an isolated vocal rather than the full mix: a clean voice without backing music works best.
Lip sync or another ZenCreator video tool?
Which tool fits your input.
Generated pass or manual pass
The control row is the real trade: a manual pass gives you frame-level correction and a generated pass does not, so work needing phoneme-by-phoneme direction belongs in an animation timeline. If the portrait does not exist yet, create it in the AI Photo Generator first.
Rights, consent, and what you can publish
Rights and consent
Lip sync work involves someone's face and voice, so rights come first. You must own or hold the rights, licenses, permissions, and consents for what you upload and how you intend to use it. Where a real person's image, likeness, voice, identity, or personal attributes are involved, you need the permissions and consents required by applicable law and by that intended use. Prompts and uploaded images are screened automatically before generation.
Commercial use and policies
Commercial use is permitted under the ZenCreator Terms and Conditions, subject to your compliance, applicable rights, and the terms governing the service and source materials; outputs are non-exclusive. The ZenCreator Content Policy sets the boundaries. ZenCreator is operated by Dimeris Ltd.
Lip sync online in your browser
Nothing to download and nothing to configure on your machine — open the tool, upload a photo and a voice track, and see what the first generation gives you before you plan an edit around it.
ZenCreator pricing
| Package | Credits | Price | Per credit | What's included |
|---|---|---|---|---|
| Starter | 200 credits | $19.99 | ~$0.100 per credit | All tools included · Credits never expire |
| Creator | 550 credits | $49.99 | ~$0.091 per credit | All tools included · Credits never expire · Priority support |
| Influencer | 1,200 credits | $99.00 | ~$0.083 per credit | All tools included · Credits never expire · Priority support |
| Professional | 6,300 credits | $499.00 | ~$0.079 per credit | All tools included · Credits never expire · Dedicated support |
One credit balance works across every ZenCreator tool, and credits never expire. Larger packs cost less per credit. Pay by card or crypto. See all packs, payment methods and policies on the pricing page.
Questions before your first run
Do I need to download a lip sync app?
No — the lip sync generator runs inside the ZenCreator studio in a desktop browser, so there is nothing to install and nothing to keep updated on your own machine. You open the tool, upload your media, and work in the browser you already have open. What you need locally is a current desktop browser and the source files you want to use.
What do I need to upload?
Two files, plus an optional prompt: one photo with a single person in it (JPG or PNG) and the voice track its mouth movement should follow (MP3 or WAV). What you upload matters more than how much — a sharp portrait taken from the front or at a ¾ angle, in clear light, with no sunglasses or mask over the face, and a clean voice recording without background music give the tool the most to work with.
Does the photo need to show the expression I want?
No. A neutral, clear portrait is the best starting point. The expressions and emotion in the video come from your voice track and the optional prompt, not from the photo, so one calm headshot can carry a cheerful read as well as a serious one.
How long is the talking video?
As long as your audio. The length is set automatically by the voice track you upload, so trim it to the line you want the picture to speak. Cut long silent gaps as well: they make it harder for the lips to stay in sync.
Can a photo with several people talk?
LipSync currently animates one person per video. Use a photo with a single face in it; if your best shot is a group photo, crop it to the person who should speak before you upload it.
Can I use a real person's face or voice?
Only where you hold the rights to it. You need the permissions and consents required by applicable law and by your intended use for that person's image, likeness, voice, identity, and personal attributes, and you are responsible for the content you upload and for how you use, share, store, or distribute the output. The ZenCreator Content Policy sets out the rules that apply, including those covering real people.
Can I publish lip sync clips commercially?
Commercial use is permitted under the ZenCreator Terms and Conditions, subject to your compliance, applicable rights, full payment of applicable fees, and the terms governing the service and source materials. The license is non-exclusive: similar or identical outputs may be generated for other users, so a generated concept or style is not exclusively yours. Read the Terms and Conditions before you publish commercially.
How are generations charged?
Generations are charged in ZenCreator credits. Current credit costs are on the Pricing page rather than here, because they change. If you are planning a run of variants, check the cost of a single generation there first and scale from that.
Can I increase the resolution of the finished clip?
Yes, as a second step. Upload the finished clip to ZenCreator's Video Upscaler, choose the available engine and output setting, and it processes the video frame by frame to raise resolution and visible detail. Motion-aware enhancement is designed to keep motion smooth rather than to guarantee an identical result, and heavy blur or strong compression in the source will limit what any upscale recovers. Plan it as two runs.
Your next clip can say something else
Upload the photo you already have, add the read it should follow, and generate an AI lip sync video you can take straight into your edit — no shoot, no keyframing, and the same photo is ready to run again the next time the script changes.